1 October 2026
Background Task Scheduling: A Reliability Guide for Backend Jobs
Background task scheduling is the process of deciding when backend work becomes due and making sure that work has a safe path to completion. A timer alone cannot do that. For a reliable system, I would give each due occurrence a durable identity, hand substantial work to a queue, make its effects repeatable, and decide in advance what happens when a run fails, overlaps, or arrives late. A scheduler tells you when to try; it does not guarantee exactly-once business outcomes. Google Cloud's Scheduler documentation explicitly describes at-least-once delivery and possible duplicate invocations.
This guide is about server-side jobs, such as reports, billing reconciliation, and scheduled AI processing. Browser idle callbacks and mobile operating-system background APIs solve different scheduling problems.
Table of contents
- Separate the schedule from the work
- Choose a trigger that matches the business clock
- Give every due occurrence its own identity
- Treat duplicate delivery and overlapping runs as separate problems
- Retry only while the result is still useful
- Decide what downtime means before the first outage
- Make time zones and clocks explicit
- A db3.ai example: schedule a repeatable latest-snapshot job
- Observe completion, then test the awkward boundaries
- A short design checklist
Separate the schedule from the work
A reliable scheduled job has at least four distinct objects or transitions:
- Schedule definition: The rule, such as “refresh the report at 09:00 UTC each day.” It says what should become due, not whether a worker ran.
- Due occurrence: One logical firing of that rule, identified by the schedule name and intended time. Save this identity before treating it as completed work.
- Claim and dispatch: One scheduler process wins the right to act on the occurrence, then hands the work to a queue. A successful claim is not necessarily a successful dispatch.
- Worker execution and result: A worker claims the queued job, performs the operation, and records success, retry, deferral, or terminal failure.
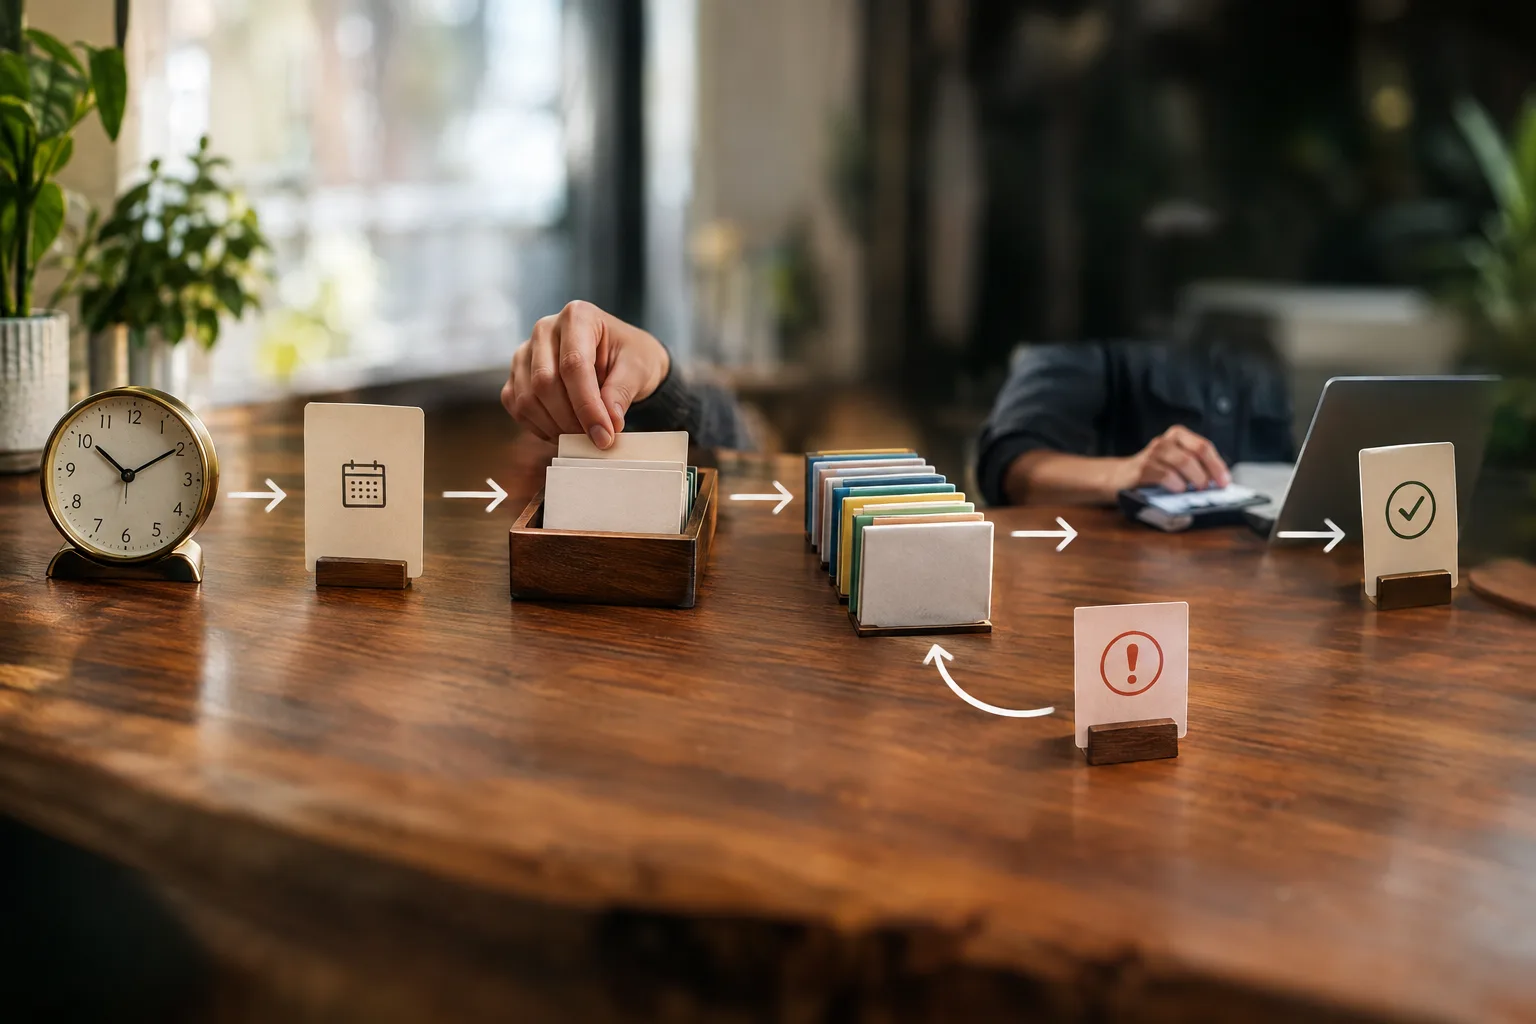
Suppose a daily report is due on Monday at 09:00. If the scheduler claims that minute and crashes before enqueueing, the occurrence exists but the worker has nothing to do. If the worker writes the report and crashes before recording success, another attempt may write it again. These are different gaps with different recovery procedures. Microsoft's background-job design guidance calls out duplicate execution, overlapping schedules, and the need to track completion rather than merely starts.
In db3.ai, Scheduler records an occurrence and can dispatch a Queue job. The documentation also warns that its claim and queue dispatch are separate transitions. Use the linked guides for installation and worker setup; here we focus on the decisions your application must make around that boundary.
Choose a trigger that matches the business clock
Not every delayed job needs a recurring calendar rule. Begin with the event that makes the work necessary, then decide whether an elapsed duration or a local date matters.
| Trigger | Good fit | Decision that affects reliability |
|---|---|---|
| Fixed interval | Refresh a cache or poll an upstream system periodically | Can an older refresh be skipped when a newer one is already due? |
| Calendar recurrence | Generate a daily report for a business day | Which time zone defines that day, and what if its local time does not occur? |
| Event plus delay | Send a reminder some time after a user action | If the user cancels or edits the action, should the pending job be invalidated? |
| Periodic reconciliation | Find orders or records whose expected follow-up work is missing | Which durable record proves completion, and how far back should the scan look? |
An event plus delay should follow the event's identity, not masquerade as a global daily schedule. Reconciliation is a safety net, not a replacement for promptly dispatching the original work. Microsoft's guidance distinguishes event-driven and schedule-driven triggers; the reconciliation pattern adds an application-owned check for work that a trigger did not finish.
Capability matters: db3.ai's documented Scheduler supports minute, hourly, and daily definitions, including daily times with an IANA time zone. Its Scheduler guide does not document arbitrary cron expressions or weekly and monthly schedules. Model event-triggered delays through the appropriate queue or application path rather than assuming every trigger fits that Scheduler API.
Give every due occurrence its own identity
A useful identity is scheduleName + scheduledForUtc, optionally combined with a tenant or business entity when the definition produces separate work per entity. Use the intended firing time, not the moment a worker finally starts. Store a unique constraint on the fields that define one logical occurrence. This stops two scheduler processes from claiming the same occurrence independently, but it does not undo side effects from a worker retry.
Keep a record of the scheduled time, claim time, queue job ID, start and finish times, attempts, current state, and last error. Store the business date separately if it has meaning beyond the UTC firing minute. A schedule definition may change later, so record enough context to explain why an earlier run was due. If you change a job name or the meaning of its payload, plan how old queued work will still be read by new workers.
Here is a small TypeScript helper for an application-owned key, not a call to the db3.ai Scheduler API:
function occurrenceKey(
  scheduleName: string,
  scheduledFor: Date,
  reportId: string,
): string {
  const minute = new Date(
    Math.floor(scheduledFor.getTime() / 60_000) * 60_000,
  ).toISOString();
  return `${scheduleName}:${minute}:${reportId}`;
}
Have the database enforce uniqueness for that logical key. The caller must pass the original scheduled instant; substituting new Date() during a late retry would give the same work a different identity. This follows the same principle as Cloud Scheduler's scheduled-time header, which remains constant across retry attempts. In db3.ai, a scheduled occurrence is claimed by its stable name and UTC minute; do not assume the helper above changes the framework's internal claim behavior.
Treat duplicate delivery and overlapping runs as separate problems
Idempotency protects a business effect when the same logical occurrence is attempted again. A unique report artifact keyed by business date can make a rerun a replacement rather than a second report. For a payment or email, use an application-owned operation key and the downstream service's documented idempotency mechanism when available; a local “already sent” flag alone cannot resolve a timeout that happened after the provider accepted the request. Reconcile the provider's outcome before repeating an ambiguous action. Google's at-least-once delivery guidance makes that distinction important even for a managed scheduler.
Overlap control handles different occurrences running at the same time. If a job runs every hour but takes 90 minutes, choose one policy: permit concurrent runs for independent partitions, skip a stale refresh, queue the next run, or prevent overlap with a lease. A lease limits concurrent ownership, but a crashed worker can lose its lease after performing an external effect. Keep idempotency even when you also have a lock.
Kubernetes makes the trade-off explicit in its CronJob concurrency policies: allow, forbid, or replace an overlapping Job. These are examples of policy choices, not features to assume db3.ai Scheduler implements automatically. Write down the policy for each workload, especially if a late report must not overwrite a more recent one.
Retry only while the result is still useful
Classify failure before retrying. A brief network interruption or explicit rate limit may be transient; malformed input, invalid credentials, or a deleted business record usually require repair or a terminal outcome. Put limits on both attempts and elapsed time, apply bounded backoff with jitter where retries could synchronize, and keep the original error available to operators. Microsoft's transient-fault guidance recommends matching retry strategy to the actual failure and operation.
There are two clocks to consider: the retry budget, which bounds how long the current occurrence can try, and the next scheduled occurrence, which may already be due. Retrying yesterday's daily report after today's report starts might be correct for an accounting ledger and wrong for a latest-only cache. Make the worker check that business rule before an irreversible effect.
In db3.ai, Queue documents maximum tries, linear or exponential backoff, jitter, and a retry-until window. A deliberate provider backpressure signal can defer a job without consuming an ordinary attempt; it still needs an application deadline so the job does not wait forever. A terminal failure needs inspection and an intentional repair or replay, not an unbounded loop.
Decide what downtime means before the first outage
When the scheduler is unavailable, “run everything we missed” is only one possible policy:
- Catch up: Run each missed occurrence independently when every period matters, such as a daily financial export. Cap the backlog and verify inputs still exist.
- Skip: Drop occurrences past a freshness deadline, such as obsolete cache refreshes. Keep a record that they were skipped.
- Coalesce: Produce one current-state update instead of many redundant snapshots. Do not use this when each earlier period must be auditable.
- Reconcile: Compare expected results with durable business state and schedule only missing work. This is especially useful when a claim succeeded but dispatch did not.
Use a persisted checkpoint or equivalent coverage record if replacing the scheduler process must revisit elapsed minutes. db3.ai's Scheduler worker can cover elapsed UTC minutes, but its restart recovery requires an application-owned durable checkpoint. Without that checkpoint a new process begins at its current minute; an isolated runDue() evaluates only the minute supplied. Catch-up also follows current schedule definitions, so changing a definition during downtime needs an explicit business decision about historical work.
Recovery is not complete when the checkpoint advances. Inspect claimed occurrences that have no queue ID, old queued jobs that never started, and terminal failures whose replacement job later succeeded. In db3.ai, replay produces a new linked queue identity while leaving the original failed occurrence in the audit record. A reconciliation pass should use both identities rather than rewriting history. Kubernetes' missed-run deadline documentation is another reminder that a platform's catch-up behavior depends on its configured policy.
Make time zones and clocks explicit
For interval work, anchor the cadence to elapsed time. For calendar work, store an IANA zone such as America/New_York alongside the intended local time, then record the resolved UTC instant for each occurrence. Daylight-saving transitions can remove a local time or cause it to happen twice. Choose whether a business-day task skips, moves, or runs once across those transitions; a UTC minute's uniqueness does not automatically mean one result per local business date.
Policies vary across products: Amazon EventBridge Scheduler skips a nonexistent spring-forward cron time and runs once at a repeated fall-back time, while db3.ai's Scheduler documentation says a repeated local time can map to two UTC minutes. Do not import another platform's daylight-saving semantics by assumption. Test both transitions for your chosen zone, keep scheduler hosts' clocks synchronized, and distinguish the scheduled instant from queue start and completion timestamps.
A db3.ai example: schedule a repeatable latest-snapshot job
For a latest-only report, the useful business effect may be replacing one snapshot, not creating one artifact per calendar day. This compact example uses the documented @db3.ai/app queue and scheduler surfaces. It assumes your application is booted, storage is configured, queue and occurrence tables are migrated, and a scheduler process plus queue worker are running. Place registration in the shared bootstrap used by those processes.
import { QueueableJob } from '@db3.ai/app/queue';
import { app } from '@db3.ai/app/server';

export class RefreshLatestReportJob extends QueueableJob {
  static readonly jobName = 'reports.refresh-latest.v1';

  constructor() {
    super({});
  }

  async handle(): Promise<void> {
    const source = await app().storage.readToString('reports/source.txt');
    await app().storage.write('reports/latest.txt', source);
  }
}

// In your shared bootstrap, after the application is available:
app().queue.registerJob(RefreshLatestReportJob);
app().scheduler.job(RefreshLatestReportJob)
  .dailyAt('09:00')
  .timezone('UTC');
The handler replaces the latest file rather than appending output. That is a design illustration, not an atomic file-write or exactly-once guarantee. If older and newer runs could race, enforce an application-level version check before publishing the final snapshot. If every business date needs its own immutable report, pass a stable date through an application-owned job design and deduplicate the output by that date; this zero-argument example is intentionally not that ledger. The Scheduler guide's executable daily example covers database setup, registration, and evaluation in full.
Observe completion, then test the awkward boundaries
We would monitor expected occurrences against due, claimed, queued, running, deferred or retrying, succeeded, and failed states. Alert on a missing occurrence, a claimed occurrence without dispatch, excessive queue wait, a stale running lease, and an overdue result, not just on thrown exceptions. Correlate the schedule name and intended minute with the queue job ID and application result. Microsoft's background-job guidance specifically recommends completion visibility, missed-schedule alerts, and queue wait measurements.
Test with a fixed clock: evaluate the same minute twice; stop between claim and dispatch; stop after an external write but before completion; restart across several missed minutes; let one job run past its next scheduled time; and exercise both daylight-saving transitions. Check what operators can see and safely replay in each case. A passing happy-path timer test does not establish these recovery properties.
A short design checklist
Before shipping, I would require an answer to each question: What creates the trigger? What identifies the intended occurrence? Where is the durable claim? What happens between claim and enqueue? Which side effects tolerate replay? What is the overlap policy? When do retries expire? Which missed runs are useful? Which time zone defines a business day? What alert fires if nothing runs?
If you are implementing this in a TypeScript application, start with the db3.ai Scheduler guide for the actual setup, then exercise its Queue worker and failure paths with a deliberately repeated occurrence. The goal is not to make a timer fire perfectly. It is to make every due piece of work explainable, recoverable, and safe when reality differs from the schedule.