2 October 2026
Scheduled Jobs in TypeScript: 7 Steps to Ship Reliable Recurring Work
A scheduled TypeScript job is reliable only when you can answer three questions: what was supposed to run, what actually ran, and what should happen if the two differ? I separate the recurring rule from a durable due occurrence and from the queued job that does the work. Then I test duplicate delivery, overlap, downtime, and failure before trusting the schedule in production. A timer firing on time proves none of those outcomes. Google's Cloud Scheduler delivery documentation notes that one scheduled execution can result in repeated delivery; the same defensive design is useful for application-owned schedulers.
This guide is a release procedure for server-side scheduled jobs, not another framework installation walkthrough. The running example is a daily audit that replaces a review artifact built from a source file. It has no email, payment, or other irreversible side effect. You can use the checks below to harden a more consequential job, but you must supply that job's own data, uniqueness, and recovery rules.
Before you start: Have a running TypeScript application, a persistent database, a queue worker, a supervised scheduler process, and permission to inspect their records and logs. For the db3.ai example, configure @db3.ai/app, storage, and migrated ScheduledOccurrence, QueuedJob, and FailedJob tables. Register the job in the bootstrap shared by the scheduler and worker. The Scheduler setup and executable lab show those prerequisites; do not create production tables using a disposable test-lab installer. Use an isolated database and harmless example files for the checks below.
Table of contents
- 1. Define the schedule, occurrence, and success condition
- 2. Set the recurrence and missed-run policy
- 3. Hand scheduled work to a db3.ai queue job
- 4. Protect effects from duplicates and overlapping runs
- 5. Bound retries and keep failure useful to an operator
- 6. Make process restarts and missing work recoverable
- 7. Verify observability and sign off on the release
1. Define the schedule, occurrence, and success condition
Write down the rule separately from its outcome. For our audit, the rule is 09:00 UTC daily. One due occurrence means that this named rule matched one intended UTC minute; a queue job is the attempt to produce the artifact for that occurrence. A successfully dispatched job is not a successful audit. db3.ai records claimed occurrences and correlates their queue lifecycle, but its claim and dispatch are separate transitions. A crash between them can leave a claimed occurrence with no queued job. I would give an operator a way to spot and reconcile that state, rather than treating an existing claim as proof of completion. See the Scheduler guide's occurrence and repair behavior.
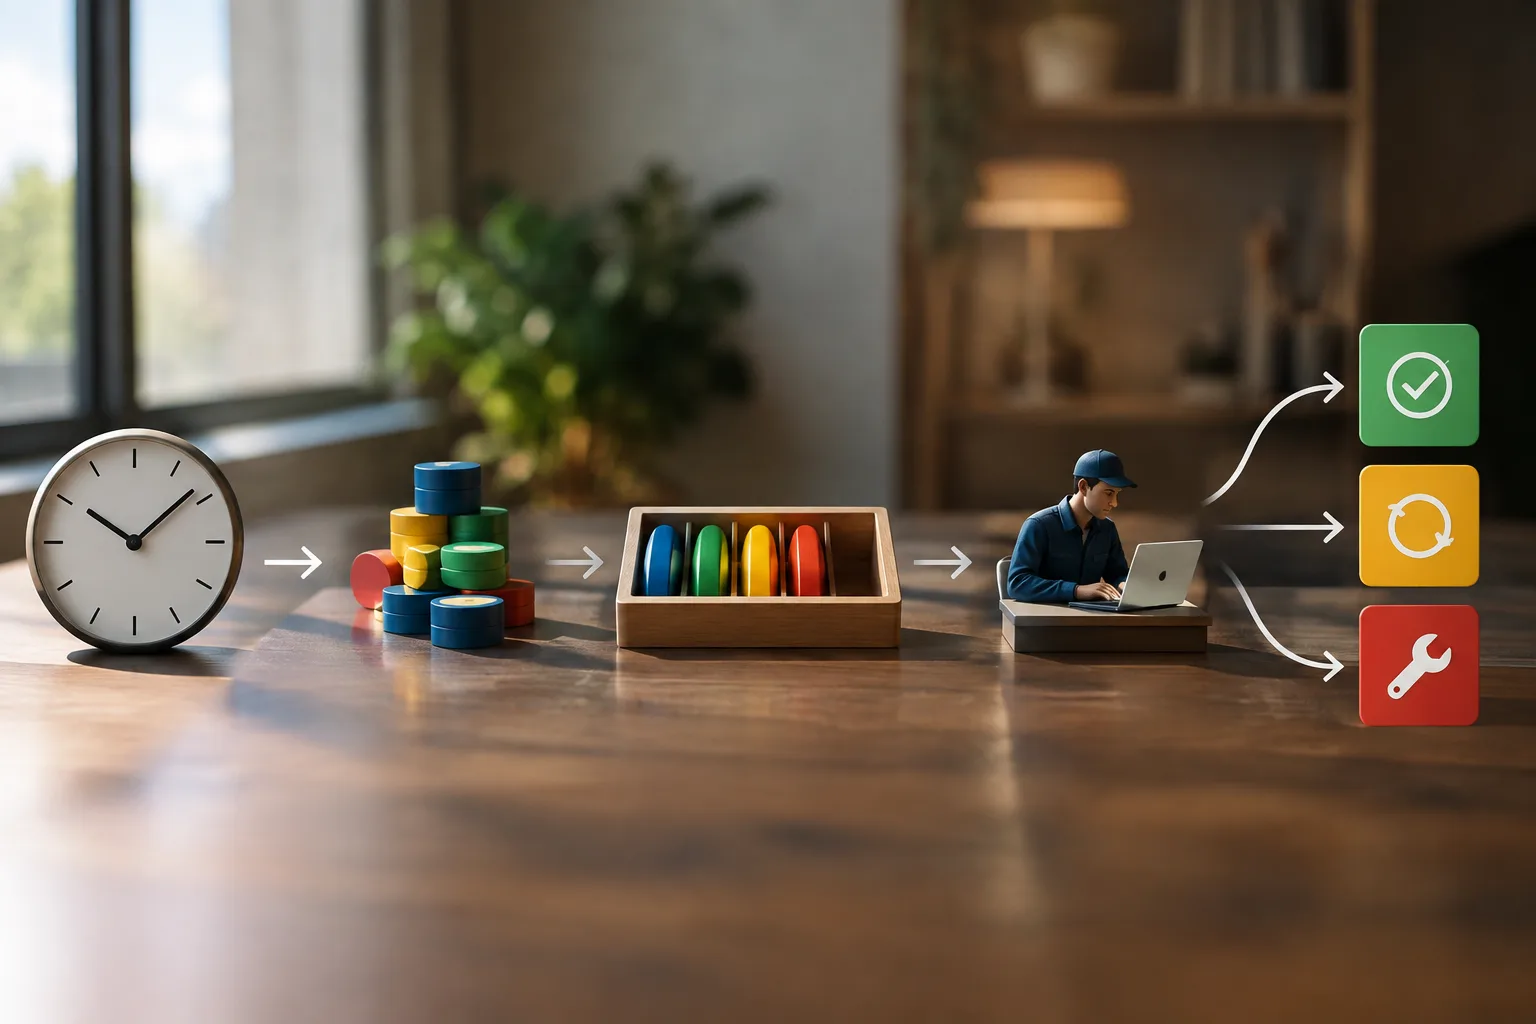
Choose an application success condition before writing a handler. Here it is: the review file contains a sorted, deduplicated list of valid open-item IDs derived from the current source. A fresh empty list is a legitimate result; a missing input is a failure, not an empty result. If this were an immutable daily financial export, I would also require a business-date key and an independently verifiable output for each date. One replaceable file would be the wrong model.
Check: An operator can point to the intended minute, occurrence state, queue identity if present, and resulting business artifact. If they can see only a scheduler log saying “started,” the outcome is not yet observable.
2. Set the recurrence and missed-run policy
Choose whether your rule follows elapsed time or a calendar clock. A minute-based poll can often skip stale intermediate work if a later poll fully reconciles current state. A daily ledger cannot skip a date simply because the scheduler was offline. State the expected response to downtime as catch up each occurrence, coalesce into one current-state run, skip with an audit record, or reconcile missing business results. Decide a backlog limit and a point after which a result is no longer useful.
For calendar work, record an IANA time zone and a business-date policy, not just a string such as 09:00. In db3.ai, dailyAt('09:00').timezone('UTC') expresses a UTC daily rule. The documented Scheduler also supports minute and hourly cadence; it does not document arbitrary cron expressions or weekly/monthly schedules. A local time that disappears during daylight-saving transition will not fire at that wall-clock minute, while a repeated local time can match two distinct UTC minutes. If the business wants exactly one result per local date, enforce that rule using an application-owned business-date key. Scheduler timing and checkpoint behavior explain the distinction.
Check: Write down the expected result for a 20-minute outage, a two-day outage, and both daylight-saving transitions in your selected zone. Test the resulting instants with fixed clocks, not a test that sleeps until tomorrow. If you cannot say which business date owns a repeated local time, use UTC until you can.
3. Hand scheduled work to a db3.ai queue job
The scheduled callback should not be your long-running audit. A queue worker gives work its own claim and failure lifecycle; a scheduler identifies when to create it. In an application where storage is already configured, this small job reads a JSON array and writes a deterministic review file. Both input and output paths are application-owned examples. The explicit validation prevents a malformed input from silently becoming a successful empty audit.
import { QueueableJob } from '@db3.ai/app/queue';
import { app } from '@db3.ai/app/server';

export class BuildOpenItemsReviewJob extends QueueableJob {
  static readonly jobName = 'audit.open-items-review.v1';

  constructor() {
    super({});
  }

  async handle(): Promise<void> {
    const raw = await app().storage.readToString('audit/open-items.json');
    const parsed: unknown = JSON.parse(raw);
    if (!Array.isArray(parsed) ||
        !parsed.every(id => typeof id === 'string' && id.length > 0)) {
      throw new Error('Expected an array of nonempty open-item IDs.');
    }

    const ids = [...new Set(parsed as string[])].sort();
    await app().storage.write(
      'audit/open-items-review.json', JSON.stringify({ ids }),
    );
  }
}

// In the bootstrap shared by scheduler and queue-worker processes:
app().queue.registerJob(BuildOpenItemsReviewJob);
app().scheduler.job(BuildOpenItemsReviewJob)
  .dailyAt('09:00')
  .timezone('UTC');
The class's stable jobName identifies the stored work; its zero-argument constructor makes it suitable for direct scheduler registration. This follows the documented Scheduler registration pattern and Queue job contract. Deploy a worker that can still resolve queued job names before renaming classes. The file write here is a replaceable example, not an atomic publish or an exactly-once guarantee. A production artifact shared by concurrent runs needs a version check or another application-level publish guard.
Check: In an isolated test app, write ['A1', 'A1', 'B2'] to the source, evaluate a fixed 09:00 UTC minute with runDue(), and let the queue worker process the job. The output should contain {"ids":["A1","B2"]}. Evaluate the same minute again: the documented unique occurrence claim should skip duplicate dispatch. Then replace the input with malformed JSON and verify that the worker reports failure instead of replacing the last good output. The Scheduler's fixed-clock test lab supplies the full database and runner wiring; the assertions above are your application's extra acceptance criteria.
4. Protect effects from duplicates and overlapping runs
A duplicate attempt and an overlapping occurrence are different hazards. The first might rerun the same job after a worker loses its lease; the second occurs when yesterday's or this morning's work is still running as the next due minute arrives. Microsoft's background-job guidance calls out both repeated processing and schedules that overlap longer-running work.
For a consequential operation, define a stable business key such as tenantId:reportDate:exportVersion and enforce its uniqueness in your application database. Use the same key through retries and replays; a newly generated queue ID is not the same business identity. Where a provider supports idempotency keys, send the business key to that provider as well. If an API times out after accepting a charge or message, a local “not completed” flag does not prove it is safe to repeat. Query or reconcile the provider result first. The example review file avoids a second appended record on an immediate repeat, but it cannot prevent an old concurrent run from overwriting a newer one.
Choose an overlap rule per workload: allow independent partitions to proceed, hold the next run, skip an obsolete run with a recorded reason, or serialize by business key using an application-owned lease and fencing/version check. A lease can expire after an external effect has happened, so it does not replace idempotency. Neither a unique scheduler occurrence nor queue lease fencing promises exactly-once side effects.
Check: Start two attempts with the same business key and two different due occurrences that target the same output. Verify one logical business result for the duplicate, then prove an older completion cannot replace the newer result. If it can, add the publish guard before launch.
5. Bound retries and keep failure useful to an operator
Separate temporary problems from work that cannot succeed as written. A short provider outage or explicit backpressure may warrant another attempt. A malformed record needs repair, not hours of retries. Budget both attempt count and useful lifetime; if a retry could run after the next schedule, decide whether its result is still valid. Microsoft's transient-fault recommendations advise matching backoff and jitter to the operation rather than retrying every error immediately.
In db3.ai, Queue documents maxTries, a retryUntilSeconds window, linear or exponential backoff, and jitter. A deliberate QueueRetryLaterError defers for provider backpressure without spending an ordinary attempt. That makes an application deadline essential, since repeated deferrals can otherwise keep work alive indefinitely. The backpressure retry cookbook shows the separate deadline. Select the policy at the Queue dispatch or job policy boundary documented for your application; do not assume a Scheduler fluent timing method also configures retries.
On terminal failure, retain the original error and job identity. db3.ai's retryFailed() creates a linked replacement and leaves the original failed occurrence failed for audit. Do not present that replacement as if the original completed successfully. First fix the missing input or provider condition; then replay intentionally and verify the replacement's output. A claimed occurrence with no queue ID requires a different reconciliation path from a terminally failed queued job.
Check: Make the example input unreadable or invalid. Confirm that you can see an error, bounded attempts, and a terminal record. Restore valid input, run an authorized replay, and confirm both the new successful outcome and the retained original failure. Test that stale work stops at its deadline.
6. Make process restarts and missing work recoverable
A long-running scheduler can evaluate elapsed minutes, but durable recovery across a replacement process needs a checkpoint that the application persists. db3.ai documents an application-owned SchedulerCheckpoint: its load method establishes or retrieves the last fully evaluated minute, and save advances it only after evaluation. Without one, a fresh worker starts in its current minute. A one-off runDue() evaluates only the specified minute. Catch-up also uses the current definitions, so a rule changed during downtime may need separate business-date reconciliation. See Scheduler restart and history guidance.
Treat the checkpoint as coverage of evaluation, not proof of business completion. After restart, compare expected business outputs with actual outputs, claimed occurrences, queued identities, and terminal failures. In particular, flag a claimed occurrence without a queue ID and a long-queued job that no worker has taken. Never simply delete an orphaned claim and fire the schedule again if its side effect might already have happened. Record the repair decision and who authorized it.
Check: In a disposable environment, stop the scheduler before one due minute, restart it with the shared checkpoint after several more minutes, and inspect which minutes were evaluated. Separately simulate a claimed-but-not-dispatched record and verify your repair workflow reports it. If changing the schedule definition invalidates historical catch-up, reconcile business outputs explicitly rather than trusting the new rule to reconstruct the old one.
7. Verify observability and sign off on the release
Give every log or application report a schedule name, intended UTC minute, queue job ID when available, business key, attempt, and result. Alert on missing expected occurrences, claimed without dispatch, queue wait beyond your threshold, and terminal failures, not merely on exceptions thrown by the worker. ScheduledOccurrence stores status, attempt count, timestamps, queue correlation, and last error; queue history and the business artifact answer different questions. Because completed queue jobs are removed from the active queue, retain application-owned evidence where long-term successful outcomes matter. The Scheduler history and Queue lifecycle guides explain what their respective records mean.
For a practical release gate, I would not ship until the team can demonstrate all of these in an isolated environment:
- A fixed due minute enqueues work and produces the expected business result; a non-due minute does not.
- Repeating the same minute skips a duplicate claim, while repeating the handler cannot duplicate a business effect.
- A slow older run cannot overwrite a newer result, and a worker restart leaves recoverable state.
- Transient errors retry within a bounded window; permanent errors become inspectable failures.
- A scheduler restart covers the missed minutes required by policy, with a detectable claim-to-queue gap.
- Someone can identify, repair, replay, and verify a failed result without erasing its original audit trail.
A passing checklist produces more than a timer that fires: it leaves an explainable path from due work to a verifiable outcome. To implement and exercise that path in your application, follow the db3.ai Scheduler guide for the exact bootstrap and test harness, then run the Queue worker walkthrough against your own harmless scheduled job before enabling real business effects.