6 October 2026
Event-Driven TypeScript: Contracts, Idempotency, Ordering, and Recovery
TL;DR
For a reliable event-driven TypeScript system, define versioned events as facts, validate them at the process boundary, and give every event a stable identity. Use an in-process dispatcher for immediate local reactions, but persist the handoff when another worker must eventually act. Consumers need duplicate protection, an ordering policy, and a repair path for failed delivery. TypeScript makes the contract easier to express; it cannot make a message durable or an external side effect happen exactly once.
An event can be as small as “an invoice was issued.” The interesting engineering questions start immediately afterward: Did the invoice commit before publication? What if the notification worker receives the event twice? What if it sees a payment event first? What can an operator inspect when processing stops?
I use event-driven TypeScript to mean application behavior organized around published facts and independently handled reactions, not simply Node.js callbacks or a particular message broker. Below, one billing workflow provides a common example across local listeners, durable delivery, and recovery. The goal is an understandable design that still works when the happy path does not.
Table of contents
- Events are facts, not instructions
- Give TypeScript a precise event contract
- Choose the delivery boundary before choosing an emitter
- Close the gap between the business write and publication
- Make each consumer idempotent at its own boundary
- Order only the streams that need ordering
- Define failure and repair as part of the contract
- Evolve contracts without stranding older consumers
- Test the failure path, not just a listener call
- Frequently asked questions
- Sources
- Recommended Reads
Events are facts, not instructions
A command asks the system to do something: IssueInvoice. The owner of that command validates authorization and business rules, updates the invoice, and decides whether the operation succeeded. Only then can it publish the fact invoice.issued. An email consumer might react by preparing a message; an analytics consumer might update a projection. Neither should have to infer whether “issued” actually means “someone clicked a button.”
I would give the producing domain ownership of an event's meaning and give consumers ownership of their own side effects. Include stable IDs and the minimum data required to interpret the fact. Avoid sending live database models, request objects, credentials, or mutable service instances across a message boundary. A consumer that needs current authoritative invoice details can fetch them by ID, with a deliberate policy for what happens if the record is unavailable or has changed.
The distinction matters when requirements grow. Adding a second consumer should not silently change whether issuing an invoice succeeds. Decide explicitly whether a reaction is part of the synchronous operation or separately promised background work.
Give TypeScript a precise event contract
Here is an application-owned discriminated union. The type field connects each fact to its payload shape; version names the wire format; eventId survives redelivery. aggregateId and sequence make a per-invoice ordering policy possible. This is contract code, not a publisher, database adapter, or runtime parser.
type Envelope<TType extends string, TPayload> = Readonly<{
  eventId: string;
  type: TType;
  version: 1;
  aggregateId: string;
  sequence: number;
  occurredAt: string;
  correlationId: string;
  payload: Readonly<TPayload>;
}>;

type BillingEvent =
  | Envelope<'invoice.issued', {
      invoiceId: string;
      accountId: string;
      amountCents: number;
    }>
  | Envelope<'invoice.paid', {
      invoiceId: string;
      paymentId: string;
    }>;

function summarize(event: BillingEvent): string {
  switch (event.type) {
    case 'invoice.issued':
      return `Issued ${event.payload.invoiceId} for ${event.payload.amountCents} cents`;
    case 'invoice.paid':
      return `Paid ${event.payload.invoiceId} via ${event.payload.paymentId}`;
  }
}
TypeScript narrows a discriminated union when its common literal field is checked, so the paid branch cannot accidentally read amountCents from the issued payload. The TypeScript handbook explains this narrowing behavior. I would also decide who generates the ID, whether occurredAt is an ISO timestamp, and how the producer increments the sequence. Those are application conventions, not properties the type system enforces.
Most importantly, a type annotation does not validate stored JSON. Decode and validate the envelope and payload at every process boundary. Reject malformed or unknown versions into an inspectable failure path instead of using a cast and hoping the consumer's compiled types describe the bytes it received.
Choose the delivery boundary before choosing an emitter
An in-process dispatcher is appropriate when a reaction should run now, within the producer's process, and losing an unexecuted reaction on process exit is acceptable. With @db3.ai/app, the documented Events service uses class constructors as exact runtime subscription keys. Its dispatch() awaits listeners sequentially; a rejected listener stops later listeners, while earlier effects are not rolled back. It is not a persisted event stream or a cross-process retry mechanism. The db3.ai Events guide and Events API reference establish that boundary.
For example, after an invoice has already been saved, a local reaction can add its ID to a process-local dashboard buffer. This intentionally demonstrates the dispatcher, not a durable billing workflow:
import { Events } from '@db3.ai/app/events';

class InvoiceIssuedLocal {
  constructor(readonly invoiceId: string) {}
}

const events = new Events();
const recentInvoiceIds: string[] = [];
const unsubscribe = events.listen(InvoiceIssuedLocal, event => {
  recentInvoiceIds.push(event.invoiceId);
});

try {
  // The actual invoice write happens earlier in application code.
  await events.dispatch(new InvoiceIssuedLocal('inv-7'));
} finally {
  unsubscribe();
  events.clear();
}
This standalone example assumes a matching installed @db3.ai/app package; the invoice write and application bootstrap are deliberately omitted. It has no database, worker, retry, or persistence, and I have not run it in your application. In an app, register long-lived listeners during boot on app().events rather than creating a new shared dispatcher per request; see the existing Events walkthrough for setup and lifecycle details. The class shape and listen/dispatch calls follow the published Events API.
If issuing an invoice creates a customer-facing promise to send a message later, I would use a durable queue or broker and a separately supervised worker. The db3.ai Queue guide describes its distinct job, registration, and worker lifecycle. A queue coordinates durable work; multiple independent subscribers may additionally require a fan-out topology. Do not assume that one queue job automatically delivers a copy to every service.
Close the gap between the business write and publication
Persisting an invoice and then dispatching an in-memory event leaves a failure window: the invoice can commit just before the process crashes. Sending a broker message first leaves the opposite window: a consumer can react to an invoice that never commits. I would use an outbox when that gap is unacceptable: save the invoice change and an event envelope in the same database transaction, then have a separate relay forward committed outbox entries. AWS's transactional-outbox guidance describes this dual-write problem and the pattern.
The outbox is an architectural pattern, not an automatic effect of calling app().events.dispatch() or merely putting two operations near each other. Your database transaction, relay, broker acknowledgement, monitoring, and retention policy need an explicit implementation. If the relay publishes successfully and crashes before marking the outbox entry sent, it can publish the same event again. Keep the original eventId and make the consumer safe to repeat. The transactional-outbox pattern calls out this relay duplication directly.
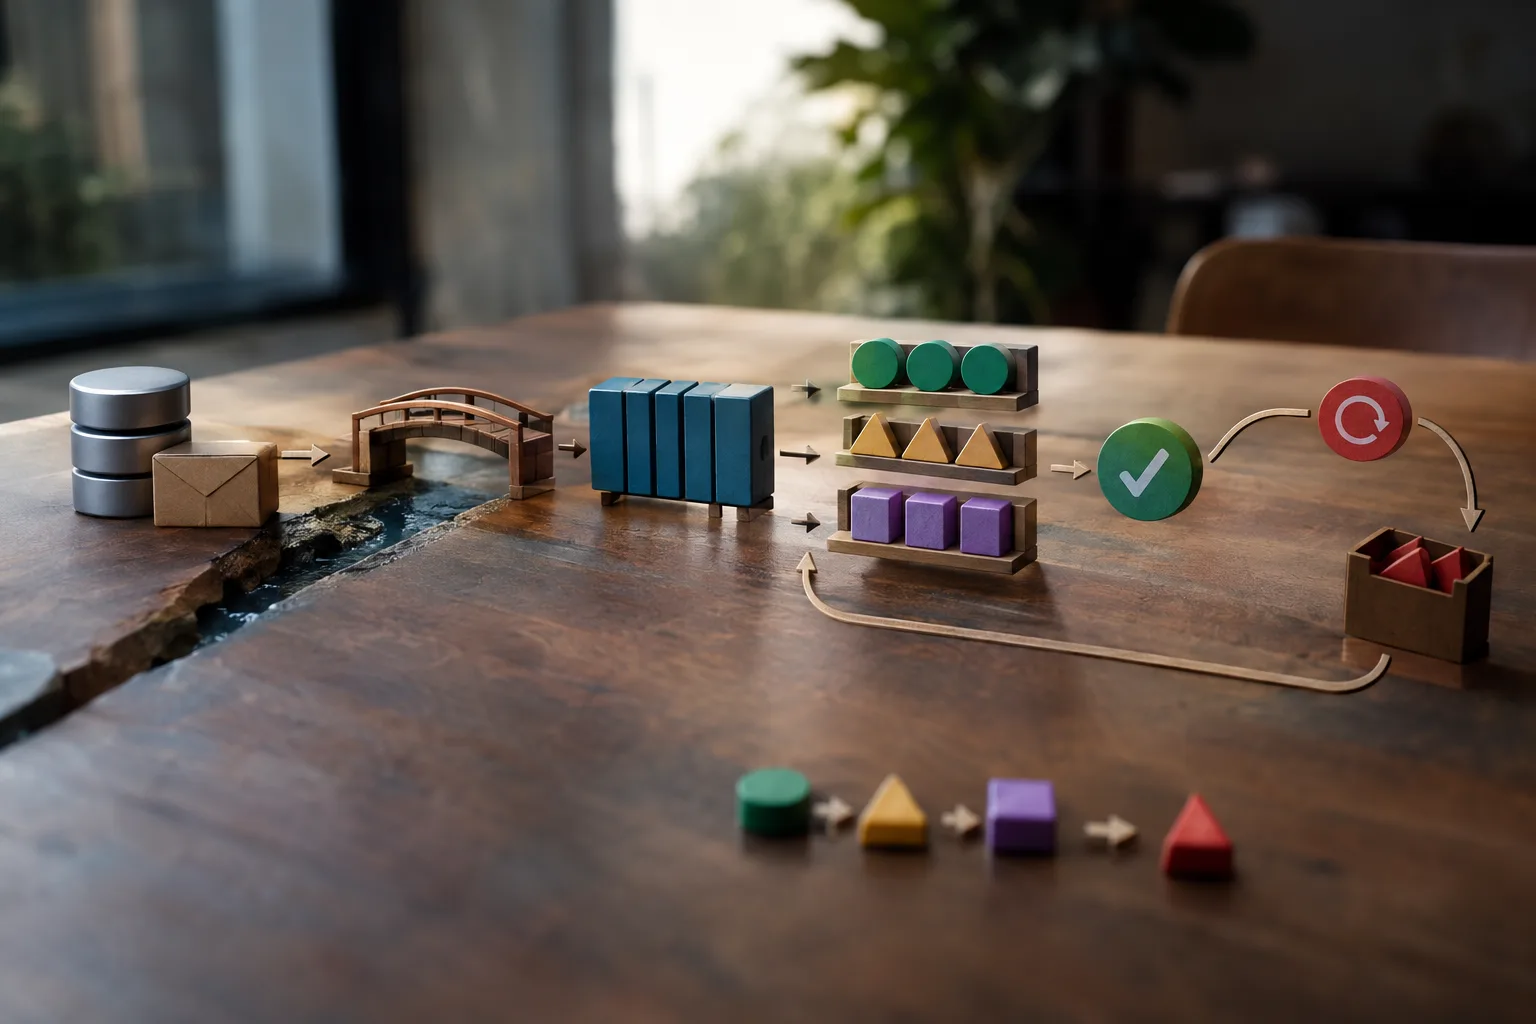
The handoff becomes recoverable when the business record and outbox entry commit together. The relay and consumers still need retry and duplicate handling.
Make each consumer idempotent at its own boundary
Suppose invoice.issued updates a ledger projection. The worker writes the projection, then loses its acknowledgement. A second delivery should not add the invoice amount again. I would give that consumer a durable record keyed by consumer identity plus eventId, with a uniqueness constraint. In one local database transaction, claim that key and apply the projection; if the key already exists, treat delivery as previously completed. Chris Richardson's idempotent-consumer pattern describes the processed-message record and transaction boundary.
That constraint is more than a preflight query. Two workers can both observe “not processed” before either writes. The uniqueness constraint and transactional update settle the race. The deduplication record must not commit before its associated local side effect; otherwise a crash could make the retry skip work that never happened.
An email provider is a different transaction boundary. A database record cannot atomically prove whether a timed-out remote request sent an email. Where the provider supports it, send a stable operation key derived from the business action, or inspect the provider outcome before retrying. For other irreversible effects, design a reconciliation procedure. “The broker delivered once” and “the customer was affected once” are different claims. AWS also warns that outbox-based notifications may be duplicated.
Order only the streams that need ordering
The invoice's issued and paid facts may need to update the same projection in sequence. Events for unrelated invoices need not wait behind each other. Use the invoice ID as the aggregate or partition key, and assign a monotonic sequence when the producer commits each state transition. This makes a local rule possible: with invoice inv-7 at applied sequence 6, accept 7; hold or reject 8 until 7 is accounted for; ignore a duplicate of 6. Store the applied sequence with the projection update, not in process memory.
A sequence field alone does not force a queue to preserve order, and a timestamp is not a substitute for an agreed producer sequence. A delayed or quarantined sequence 7 can block later updates for that invoice; decide whether to pause that stream, rebuild from authoritative state, or use a business-specific supersession rule. Do not quietly apply 8 and hope that replaying 7 later will fix the projection. Other invoices can continue if your partitioning and workers support that isolation. AWS documents that standard SQS queues may deliver more than once and out of order, which is why transport choice must match the ordering rule. See SQS queue types.
Global order is a much stronger promise than this example needs. Start by identifying which entity's transitions must be observed consistently; select a transport and concurrency policy to enforce that narrow requirement, then test its behavior under retries and worker restarts.
Define failure and repair as part of the contract
For durable delivery, acknowledgement should follow the local work that you can verify. If processing fails, leave the message eligible for a bounded retry with backoff; if the payload is invalid or retries are exhausted, move it to an inspectable dead-letter or quarantine state. Monitor message age, attempt count, and terminal failures. AWS's dead-letter-queue guidance describes inspection and redrive, including the warning that moving a FIFO message aside can break an ordering requirement.
For every failed event, I would retain the event ID, type, version, aggregate ID, correlation ID, consumer name, attempt count, and a structured error without copying secrets into logs. An operator needs a safe way to answer three separate questions: Did the producer commit the event? Did this consumer apply its local change? Did any external provider perform the effect? A trace spanning all three is more useful than an isolated “handler failed” log.
Replay is a new attempt, not a new fact. First repair code, data, or access; preserve the original event identity when retrying the same fact; verify whether its effect already happened; and authorize redrive. If a newer event has superseded an old failure, decide whether to skip or rebuild rather than replaying blindly. Keep the earlier failure record visible for audit and incident review.
Evolve contracts without stranding older consumers
A durable event may sit in storage while producers and consumers deploy different versions. Give the payload a version and keep consumers capable of reading the versions still retained in queues or replay stores. An additive optional field might be safe for an older reader, but compatibility depends on the serialization format and how that reader validates unknown fields. A changed meaning or a removed required field merits an explicit new contract and rollout plan. Confluent's schema-evolution documentation distinguishes backward, forward, and full compatibility instead of treating all changes as equivalent.
In the example union, a breaking invoice.paid payload would become a distinct versioned case. At the receiving boundary, validate its version, transform old data deliberately if needed, and test a producer-new/consumer-old deployment as well as replay with the newest consumer. A TypeScript compilation of today's code cannot check yesterday's stored JSON.
Test the failure path, not just a listener call
I would keep four tests around this workflow:
- Contract: Valid issued and paid envelopes decode into the intended versioned cases; malformed payloads and unknown versions fail visibly.
- Duplicate delivery: Send the same
eventIdconcurrently to one consumer. Assert one durable local effect, not merely one log line. - Out-of-order delivery: Deliver paid sequence 8 before issued sequence 7 for one invoice, while another invoice progresses. Assert your declared hold, skip, or rebuild behavior.
- Recovery: Stop the relay after publication but before its sent marker, and stop a worker after a harmless effect but before acknowledgement. Verify retained identity, bounded retries, quarantine, and authorized replay without a second business effect.
Keep fast unit tests for union handling and validation, then exercise the real database constraints and transport configuration in integration tests. The important result is not “my handler ran”; it is “the business outcome remains correct when the same fact is observed again.”
Frequently asked questions
Is an EventEmitter enough for event-driven TypeScript?
For local, disposable reactions it can be. If a committed business action requires another process to finish work after a crash, it is not enough by itself; choose persisted work and an explicit recovery path. db3.ai similarly separates its process-local Events from Queue jobs.
Does a typed event guarantee exactly-once processing?
No. Types describe the payload in your code, not broker delivery or atomicity with an external system. Stable IDs, transactionally protected local effects, and reconciliation at remote boundaries address those separate problems. The idempotent-consumer pattern covers the local duplicate case.
Next step: Choose one consequential event in your application. Write down its producer transaction, the identities and versions consumers receive, and exactly what each consumer does when delivery is duplicated, delayed, or fails. If you use db3.ai, begin with the typed Events guide for local reactions and the Queue guide when work must outlive the request. Neither replaces an application-owned outbox when the business write and durable handoff must be atomic.
Sources
- TypeScript Handbook: Narrowing
- db3.ai: React to a saved note (Events guide)
- db3.ai: Events API reference
- db3.ai: Queue guide
- AWS Prescriptive Guidance: Transactional outbox pattern
- Chris Richardson: Transactional outbox pattern
- Chris Richardson: Idempotent consumer pattern
- AWS: SQS queue types
- AWS: Using dead-letter queues in Amazon SQS
- Confluent: Schema evolution and compatibility
Recommended Reads
- TypeScript Job Queue: How to Choose for Retries, Concurrency, and Recovery for the next decision if your events become worker jobs.
- Message Queue TypeScript: 5 Options for Reliable Jobs and Events for comparing durable queue and multi-subscriber transport boundaries.