7 October 2026
Backend Workflow Automation: Compare Queues, Schedulers, Workflow Engines, and Integrated Runtimes
TL;DR
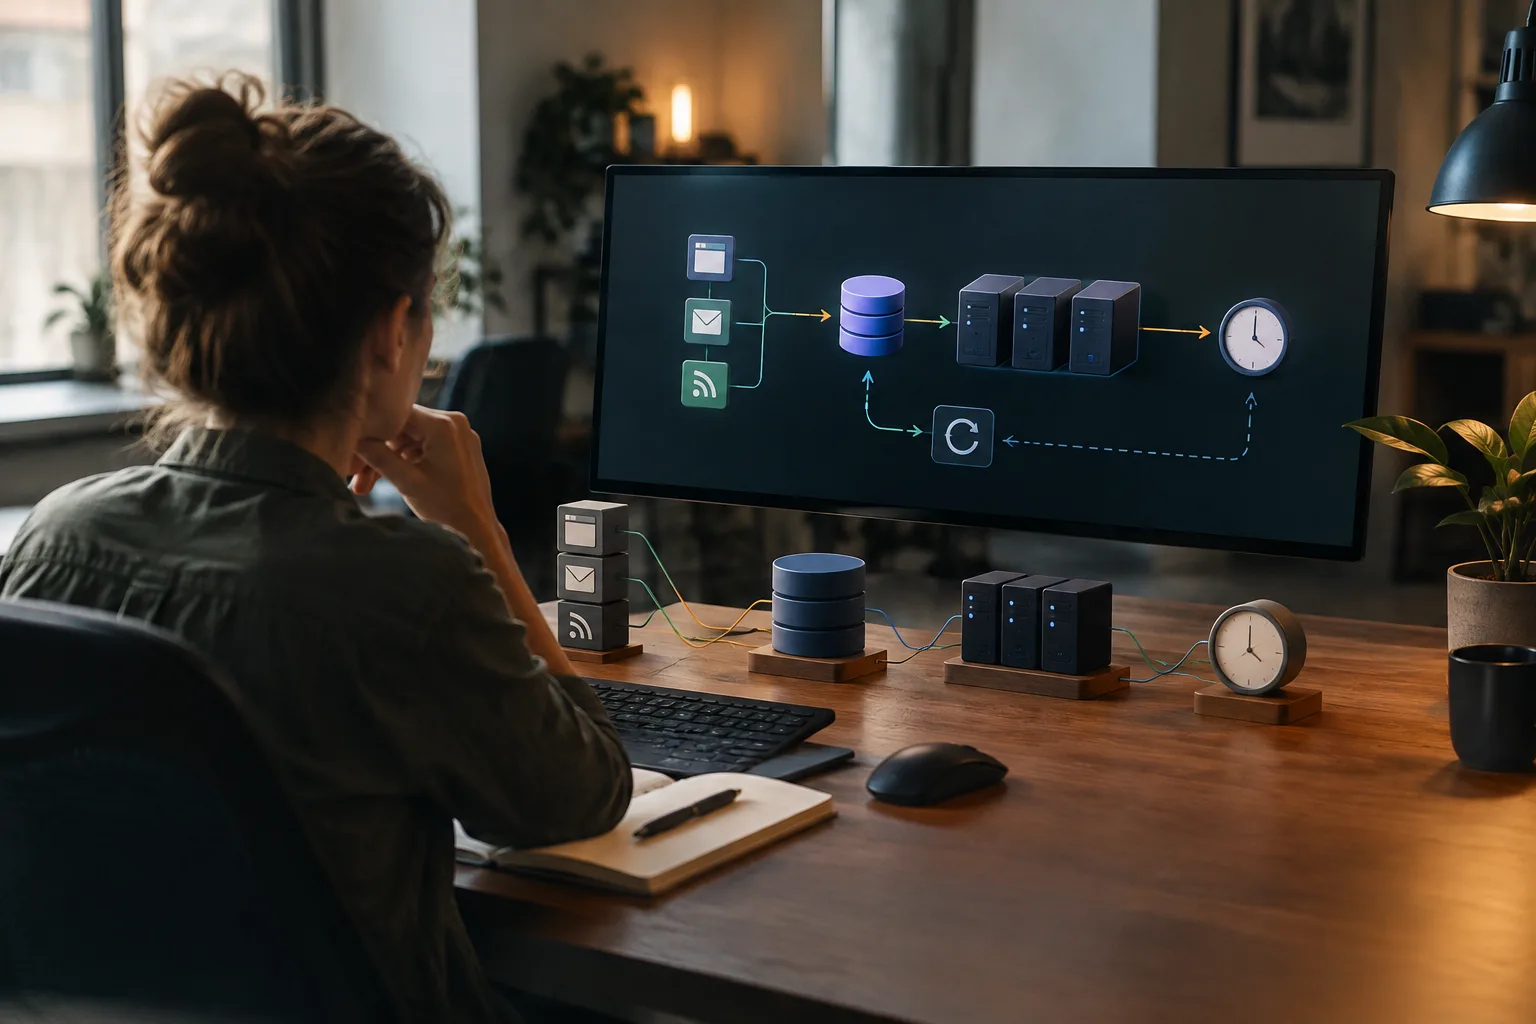
For one background action, start by evaluating a durable queue and workers. Add a scheduler when work must become due on a calendar or recurring cadence. Choose a workflow engine when several steps need persistent, inspectable progress or long waits. An integrated application runtime is worth considering when the same product needs queues, schedules, data, and storage together. None of these choices makes an external side effect happen exactly once; use business-level idempotency and test recovery.
A customer requests a report, a provider briefly rejects the request, and the result must appear tomorrow morning. That sounds like one automation, but it spans at least three decisions: what starts the work, where its unfinished state lives, and who can explain what happened after a failure. I would make those decisions before choosing a product by its feature list.
This guide is for product engineers comparing backend workflow automation for event-driven work, recurring jobs, external APIs, and AI tasks. It compares architectural approaches, not frontend workflow builders or manual approval software. Where I name a product, it is an example of an approach, not a claim that all products in that category behave identically.
Table of contents
- Define the job before comparing tools
- Compare the same boundaries in every approach
- Failure handling is a product decision, not a checkbox
- Monitor the promised result, not just the worker
- Which approach fits the next workload?
- Frequently asked questions
- Sources
- Recommended Reads
Define the job before comparing tools
Backend workflow automation is server-side coordination of work after an event, at a scheduled time, or as part of a sequence. The browser can initiate a report and display progress, but it should not be responsible for completing the report after the tab closes. Microsoft's background-job architecture guidance separates event-driven and schedule-driven triggers and recommends tracking completion independently of the UI.
Write down the unit of work first. For a report, that might be a report ID and revision. For a daily reconciliation, it might be a schedule name and intended date. For an AI request, it might be an application-owned run ID, not an HTTP connection or a queue record ID. Then ask whether a second attempt is permitted, how long the result stays useful, and which side effects can be repeated safely.
A successful enqueue means the system accepted a work item. It does not prove that a worker ran, that an API accepted the request, or that the customer received the result. The db3.ai Queue guide makes this distinction explicit for its own job IDs.
Compare the same boundaries in every approach
I use six questions for each option: trigger, durable state, retry boundary, schedule, visibility, and operational owner. They expose differences that a checklist saying “supports jobs” will hide. For example, a delayed queue item and a daily calendar occurrence both happen later, but only the latter must explain what was due while its scheduler was offline.
| Approach | Trigger and stored state | Retry and schedule boundary | Visibility and operational owner |
|---|---|---|---|
| Queue plus workers | App event or API dispatches a stored job; worker claims it. | Retry one job; add a separate calendar scheduler when needed. | Inspect waiting and failed jobs; team runs workers and queue storage. |
| Scheduler plus jobs | Clock creates a due occurrence, then hands off work. | Decide catch-up, overlap, and retry of the dispatched job separately. | Track expected occurrences and job results; team runs scheduler and executor. |
| Workflow engine | Event or schedule starts a persisted, multi-step execution. | Coordinate step-level failure and long waits, subject to the engine's model. | Inspect execution history; team operates or contracts for coordination and workers. |
| Integrated application runtime | Application services dispatch jobs and register schedules in one runtime. | Use its queue and scheduler contracts; assess how they meet multi-step needs. | Correlate application and job state; team still runs storage, scheduler, and workers. |
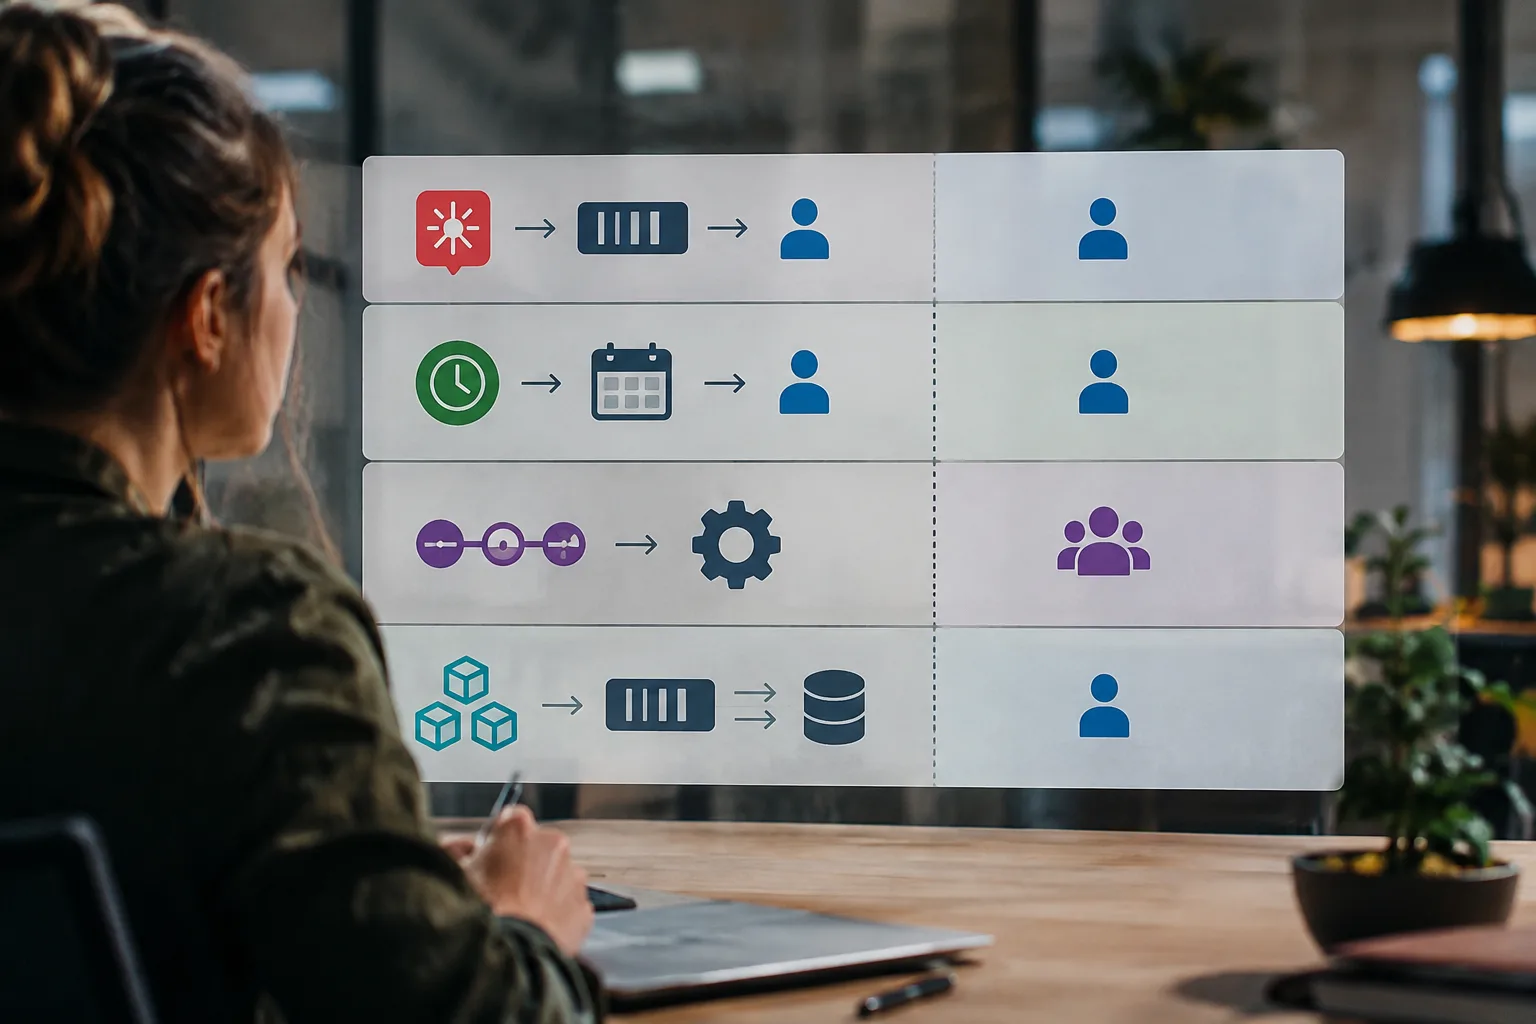
The table describes architectural responsibilities, not guaranteed performance or identical feature sets. In particular, storage durability does not make the business-record write and job dispatch atomic. If losing that handoff is unacceptable, implement and verify a transactionally backed outbox or equivalent recovery mechanism. AWS's transactional outbox guidance explains the dual-write gap and warns that a relay can still publish duplicates.
1. Queue and workers: one recoverable action
A queue is a good starting point for sending a notification, generating one report, or processing an uploaded file. A producer persists a small payload; a separately supervised worker claims it and performs the action. A dedicated library such as BullMQ documents queues, workers, delayed jobs, and retry backoff. Its queue guide shows that a worker can process a job after it has been stored; its retry guide describes attempt settings and fixed or exponential backoff.
The limitation is orchestration. If a job calls three providers in order, retrying the whole handler may repeat the first two calls. You can split it into jobs and store business progress yourself, but then your application owns each handoff, dependency, and repair path. A queue may provide chains or batches, yet those features do not automatically provide an atomic, inspectable end-to-end workflow. The db3.ai Queue guide explicitly documents a possible duplicate successor in a crash window between chained jobs.
Choose this approach when a single retry boundary is understandable and your team wants direct control of worker scaling. Ask who operates the queue datastore, how failed jobs are retained, and whether your product needs its own status record. BullMQ's documented failure retention can depend on queue configuration, so a monitoring plan cannot assume every old failure will remain available indefinitely.
2. Scheduler plus jobs: recurring work with an occurrence record
A scheduler answers when a task is due; the job system answers how it runs and recovers. For a daily report, keep the definition, intended due occurrence, queue job, and completed report distinct. A timer firing at 09:00 is not evidence that the resulting report exists.
Ask what happens if the scheduler restarts at 09:05, if two scheduler instances see 09:00, or if yesterday's report overlaps today's. Decide explicitly whether missed work should catch up, be skipped, or be coalesced, and which time zone defines the business day. The db3.ai Scheduler guide documents occurrence claims and queue dispatch as separate transitions. It also notes that restart catch-up needs an application-owned durable checkpoint and that a claimed occurrence can remain without a queued job after a crash. Those are reasons to monitor and reconcile, not reasons to assume a scheduler alone is unreliable.
This is the clearest fit when the main requirement is recurring or time-based work rather than a graph of dependent steps. An event-triggered reminder after a delay may instead be a delayed queue job; a calendar recurrence needs an explicit due-occurrence policy. For implementation details, see the site's Scheduler guide rather than treating a clock expression as a complete recovery design.
3. Workflow engine: state that spans steps and waits
Consider a workflow engine when an account-provisioning run must create a workspace, wait for verification, call another service, and recover from a failure without simply starting over. Temporal's Workflow Execution documentation describes persisted execution history, replay, timers, and activity boundaries. AWS Step Functions documents execution status and monitoring and configurable retries and catches. These are concrete examples of coordination, not interchangeable APIs.
The benefit is an inspectable execution boundary across steps. The cost is adopting that system's execution model, deployment and integration requirements, and operational or service dependency. A durable execution history does not reverse a payment or undo a provider call that succeeded just before its task result was recorded. Design idempotency or reconciliation at that external boundary.
Start here when step-level recovery, long waits, branching, or human approval is part of the product requirement. If your workload is one independently retried report, an engine can add more concepts than it removes. An AI workflow with tool calls and approval pauses may justify it; a single queued model call usually does not.
4. Integrated application runtime: jobs beside your product services
For a TypeScript product already using @db3.ai/app, I would also evaluate its integrated path. The application package documentation lists database, queue, scheduler, storage, and other application services. Its Queue guide describes database and Redis drivers, named queues, delayed dispatch, retry policy, worker registration, and failed-job replay. This is an application runtime with separately operated workers, not a hosted promise that someone else runs your jobs.
The appeal is sharing an application bootstrap and domain identifiers across the API, worker, and scheduler. The trade-off is ownership: configure the storage and queue driver, apply migrations, supervise both processes, and keep stored job payloads compatible across deployments. If a product needs durable branching or a long-lived approval state, evaluate whether the documented orchestration facilities and your application model actually meet that requirement rather than assuming that one queued handler does.
Here is a compact example of one job with two possible triggers, not a full installation tutorial. It follows the Queue guide and Scheduler guide. In an installed and booted db3.ai application, define a zero-argument, serializable job:
import { QueueableJob } from '@db3.ai/app/queue';
import { app } from '@db3.ai/app/server';

export class RefreshSummaryJob extends QueueableJob {
  static readonly jobName = 'reports.refresh-summary.v1';

  constructor() {
    super({});
  }

  async handle(): Promise<void> {
    const source = await app().storage.readToString('reports/source.txt');
    await app().storage.write('reports/latest.txt', source);
  }
}
Register the job once in the shared bootstrap used by producer, scheduler, and queue worker. Then choose whether a daily schedule creates the job or an authorized application action dispatches one immediately:
// Shared bootstrap, after the application is available:
app().queue.registerJob(RefreshSummaryJob);
app().scheduler.job(RefreshSummaryJob).dailyAt('09:00').timezone('UTC');

// Separately, inside an authorized, booted route or service:
const jobId = await app().queue.dispatch(new RefreshSummaryJob(), {
  maxTries: 4,
  backoff: {
    strategy: 'exponential',
    initialSeconds: 15,
    maxSeconds: 300,
    jitter: true,
  },
});
First configure the application database and storage, migrate queue and scheduled-occurrence tables, and run a supervised scheduler process plus a worker for the dispatched queue, as the guides describe. The source file and authorization check are application-specific and omitted here. The handler replaces a demonstration file; it does not provide atomic writes or protection from an older run overwriting a newer one. Add a business revision check for that case. jobId proves dispatch, not completion, and I have not executed this excerpt in your deployment. Check the current package installation instructions before using the imports with your installed package.
Failure handling is a product decision, not a checkbox
Imagine a worker calls an external provider, the provider completes the action, and the worker loses its lease before recording success. A second attempt might make the same call. Microsoft's idempotency guidance for background jobs describes this repeated-execution risk. I would give the operation a stable business key, use a provider-supported idempotency key when available, and reconcile ambiguous outcomes before replaying an irreversible request.
Set a bounded policy for ordinary transient failures: attempts, backoff, and a point after which a late success is no longer useful. Permanent bad input should reach an inspectable failure instead of exhausting resources forever. In db3.ai, an explicit provider-backpressure deferral does not spend an ordinary attempt, so it needs an application deadline; its backpressure example shows that boundary. Do not infer equivalent deferral semantics in other products just because each says “retry.”
Also test the producer's handoff. A business record can commit just before a separate enqueue fails; a queue configured on the same database does not automatically put both calls in one transaction. An outbox written with the business change can close that local dual-write gap, but its relay and consumers must handle duplicate publication. AWS documents both aspects in its outbox pattern.
Monitor the promised result, not just the worker
I would put four identities on one operational view: the business operation, triggering event or scheduled occurrence, job or workflow execution, and external effect. Record queued time, start time, attempts, next retry, terminal error, and application outcome. Then alert on old waiting work, an expected schedule with no occurrence, a claimed occurrence without a job, and a final failure awaiting repair. Microsoft's observability recommendations distinguish queue wait from processing time and call for missed-schedule and dead-letter monitoring.
Visibility differs by approach. A queue may expose attempts and failed records but leave customer-facing report progress to your database. A workflow engine can expose step history, yet may not know whether your product considers the run delivered. In db3.ai, Scheduler records occurrence status, while Queue's failed-job replay creates a replacement job and retains the earlier failure; the application should track its own final business result. Keep logs and status access scoped to authorized users, especially when payloads reference customer data.
Which approach fits the next workload?
| Workload | Evaluate first | Ask before committing |
|---|---|---|
| One report or file transformation after an API request | Queue and workers; integrated queue if already using the runtime | Can the result be safely retried and surfaced to a user? |
| Recurring export or reconciliation | Scheduler plus durable job | What happens to missed, duplicate, and overlapping occurrences? |
| Several dependent external API calls | Workflow engine, or explicit application state plus jobs | Which step can be retried without repeating earlier effects? |
| One AI model call | Durable job | How are provider timeout, cost, and an uncertain result handled? |
| Multi-step AI run with tools or approval waits | Workflow engine or a validated integrated orchestration design | Where do intermediate state and operator recovery live? |
The shortlist is deliberately conditional. Choose the smallest model that can explain a failed run, not merely execute a successful one. Before adopting it, run the same drill on each finalist: accept a harmless work item, stop its worker after a side effect but before completion, restart, and inspect the business result, retry record, and authorized repair path.
Frequently asked questions
When is a queue enough instead of a workflow engine?
When one stored action has a clear owner, a bounded retry policy, and a result you can record in your application. Several independent jobs can still use a queue. Move toward a workflow engine when dependencies, long waits, or step-level recovery become central to what users and operators must see. Temporal's execution model illustrates that distinct state boundary.
Can one scheduler replace a job queue?
Usually not for substantial background work. A scheduler determines when work becomes due, while a queue supplies persistent work claiming and retry behavior for workers. The db3.ai Scheduler guide deliberately hands expensive work to Queue and records both occurrence and job outcomes.
Next step: If your application already uses db3.ai, use its Queue walkthrough and scheduled-work guide to run that failure drill with a disposable job. Verify the behavior of your business write, storage driver, and provider before shipping the customer-facing result.
Sources
- Microsoft Learn: Best practices for background jobs
- AWS Prescriptive Guidance: Transactional outbox pattern
- Temporal: Workflow Execution overview
- AWS Step Functions: State machines
- AWS Step Functions: Error handling
- BullMQ: Queues
- BullMQ: Retrying failing jobs
- db3.ai: @db3.ai/app package
- db3.ai: Queue guide
- db3.ai: Scheduler guide
- db3.ai: Retry later without using an attempt
Recommended Reads
- Background Task Scheduling: A Reliability Guide for Backend Jobs for missed runs, overlap, and time-zone policy.
- Event-Driven TypeScript: Contracts, Idempotency, Ordering, and Recovery for reliable event-to-worker handoffs.
- TypeScript Job Queue: How to Choose for Retries, Concurrency, and Recovery for a deeper queue-library decision.